Alex Noonan
Senior Developer Experience Advocate
View all authors

Inside the dbt Wizard harness: building an agent that thinks in DAGs
· 15 min read
Jason Lin
Senior Software Engineer
Alex Noonan
Senior Developer Experience Advocate
Sam Ferguson
Staff Product Designer

Ask an analytics engineer to rename a column and they won't start with the SQL. They'll check what reads it downstream, which tests and dashboards will break, build only what changed, and compare the data before anyone reviews it. The dbt MCP server and agent skills can teach a coding agent those steps, but they can't make sure it follows them every time, builds on what's changed, or shows you the data diff before you review the changes.

We built dbt Wizard around a different idea. Wizard works like an analytics engineer: it thinks in DAGs, tests and fixes its own work, and keeps you in flow, so you review a working change instead of a first draft. None of that comes from the model; it comes from the harness, workflows, and UX we built around it.

Try Wizard Desktop

Run parallel agents, review data diffs and lineage next to the code, and validate changes against your warehouse. Join the Wizard Desktop waitlist.
The dbt MCP server comes to Claude: governed context, one sign-in away

· 8 min read
Alex Noonan
Senior Developer Experience Advocate

When we open-sourced the dbt MCP server in April 2025, it was an experimental, locally hosted project with a clear thesis behind it: structured data is going to be deeply integrated into AI workflows, and dbt is the layer that provides the governed context those workflows run on. Anthropic has helped validate our thesis. Naturally, it made sense to have a cloud-hosted version with remote OAuth, so you can use it with whatever AI tool you are most comfortable with.

The remote dbt MCP server now runs inside the dbt platform, and you can connect it to Claude in a minute or two by signing in and completing the authentication flow. You add dbt as a connector, approve the access you want, and Claude gains access to your governed data and rich dbt metadata.

This post walks through what the remote server brings to Claude, the types of workflows it fits into for both people and agents, and how the tools compose once they share a conversation.

No babysitting, not today

· 9 min read
Alex Noonan
Senior Developer Experience Advocate

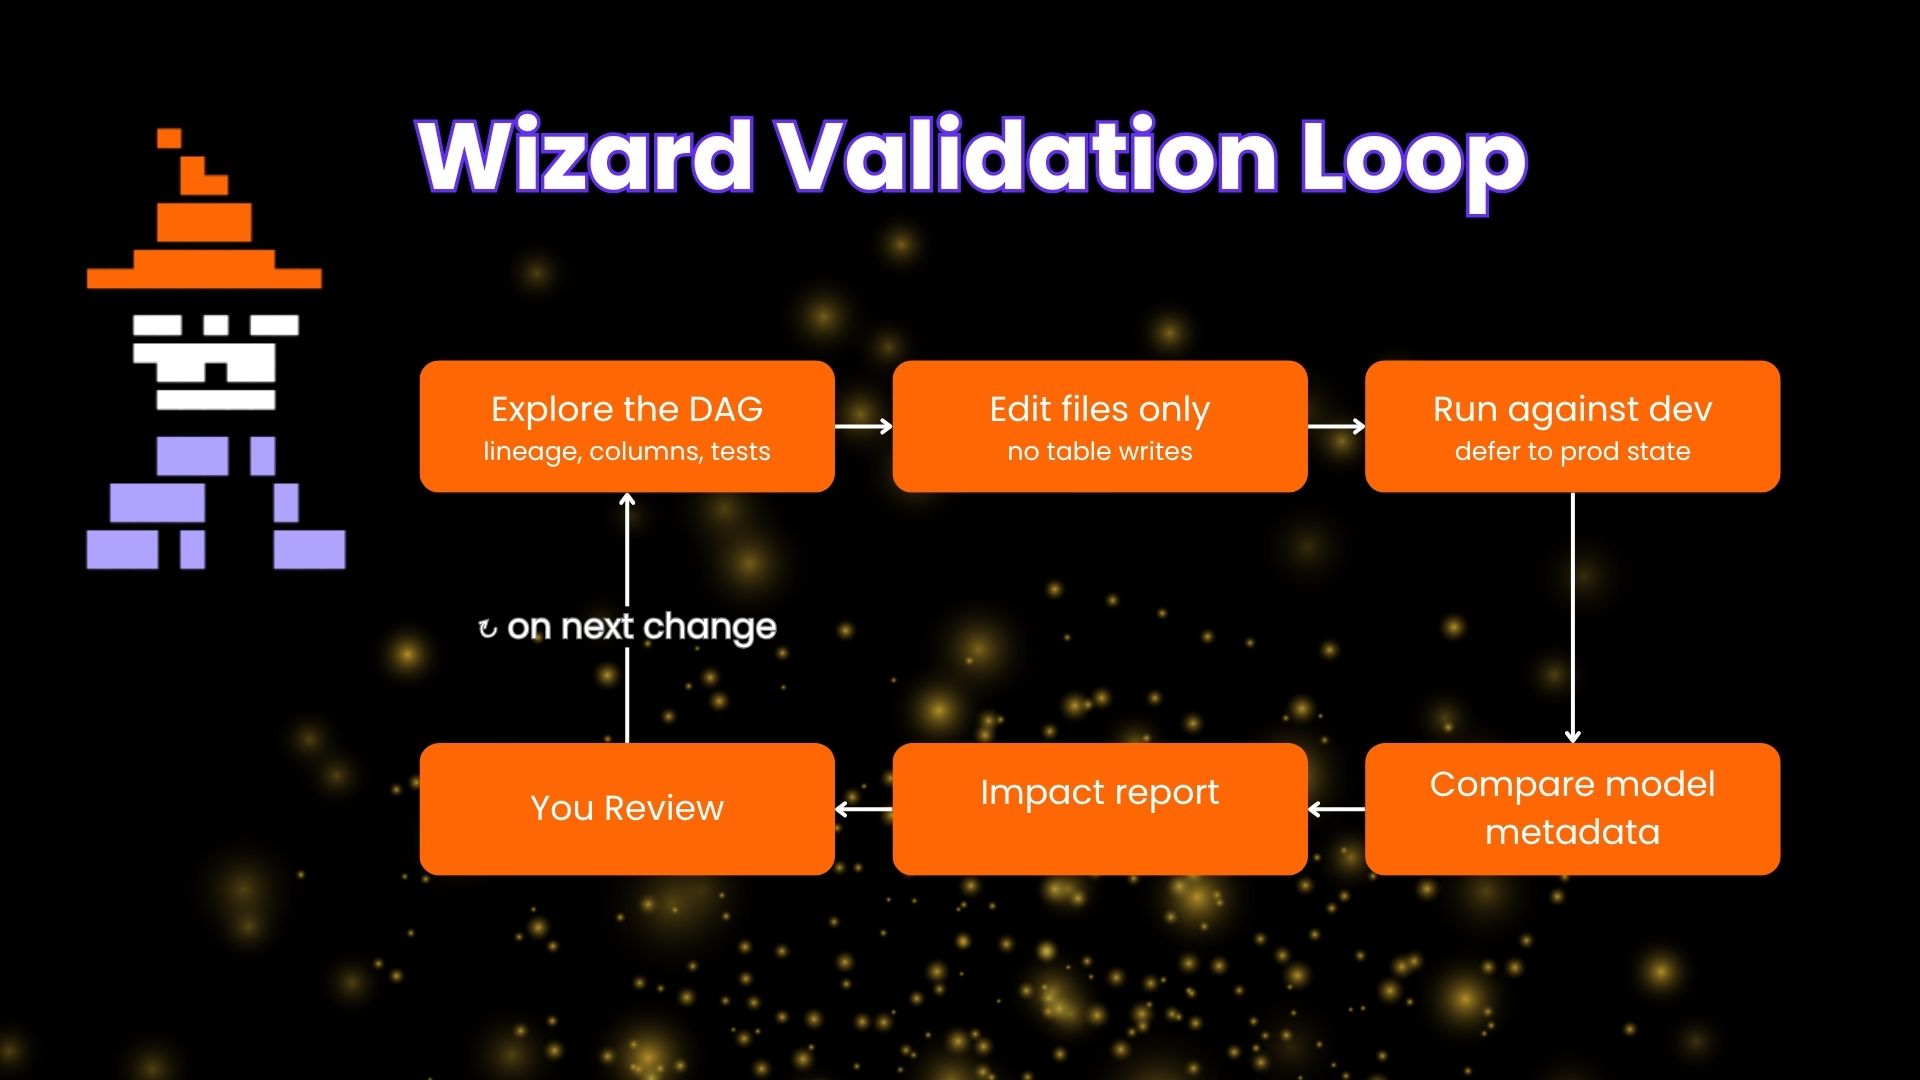
We recently released dbt Wizard, a CLI for doing agentic data work on dbt. This is a harness specifically built for data work and as such I was excited to spend an afternoon running dbt Wizard across a personal project with about 100 models or so that I've been maintaining for a while. You can use this project to see firsthand some of the differentiators for Wizard, particularly how the validation loop works.

Data projects are never done and I had a few tasks I've been putting off:

  • Migrating from MotherDuck to Iceberg + BigQuery
  • Upgrading dbt Core to dbt Fusion
  • Migrating from dbt Core to dbt platform
  • Building out a semantic layer

These are a good mix of pretty standard data work (have you done your annual migration yet?) and some dbt specific tasks. A good informal eval for the fundamental question for any dev tool: Does it work?

I was pleasantly surprised with my experience in that I didn't have to babysit Wizard or build any additional workflows on top of it. Because it has a native understanding of what a dbt project is, and its ability to set up validation subagents that match the task made it easy for me to just pop in when needed and I didn't have to babysit the whole process and I accomplished all of my objectives.

a loop showing how wizard validates changes